
DeepMind Unveils AlphaGenome 2, an AI That Reads DNA Cell by Cell to Pinpoint the Variants Behind Disease

Google DeepMind has unveiled AlphaGenome 2, a new artificial intelligence model that reads the human genome the way the body itself does — not as one flat text, but as a set of instructions interpreted differently by every type of cell. Announced on Wednesday 11 November, the model predicts how a single-letter change in DNA alters gene activity inside a specific cell type, a shift its makers say lets scientists find nearly twice as many disease-linked variants as the previous generation of the tool.
The announcement, published on DeepMind’s research blog and accompanied by a technical paper, marks the second major release in the company’s genomics programme in as many years. The first AlphaGenome, launched last year, predicted how DNA variants affect molecular activity across broad tissues. Its successor narrows the lens dramatically: instead of averaging a variant’s effect across a whole tissue, AlphaGenome 2 asks what that variant does in one chosen cell type, or in one particular state of that cell — a gut macrophage, an activated immune T cell, a maturing red blood cell.
That distinction matters because every cell in the human body carries the same DNA, yet a heart muscle cell and an immune cell fighting an infection switch different genes on and off to do their jobs. A variant that is harmless in one cell type can be decisive in another, and the signal of a disease-causing change is often drowned out when scientists look only at tissue averages. According to DeepMind, AlphaGenome 2 was redesigned from the ground up to solve exactly that problem, and on the company’s headline benchmark it identified 30 per cent of causal variants, against 16 per cent for the original model fine-tuned on single-cell data and other specialised tools.
The model is available from today for non-commercial research through the AlphaGenome API, with commercial research access in a private preview. DeepMind stresses that both AlphaGenome versions are intended for research use only and have not been validated or approved for clinical or diagnostic purposes — a boundary the company repeats in its announcement and in the technical paper.
From tissue averages to single cells
The core idea behind AlphaGenome 2 is a change of architecture. The first AlphaGenome took a DNA sequence of up to a million letters and predicted molecular activity across thousands of experiments from many tissues all at once. That parallel approach was efficient, but according to DeepMind it spread the model’s capacity thin and made it hard to capture subtle differences between closely related cell types.
AlphaGenome 2 is built differently. It is a conditional model: alongside the million-letter DNA sequence, it takes a single biological condition — a tissue, a cell type or a cell state — as an input, and feeds that condition into every stage of its architecture. It predicts the effect of the sequence for that one condition at a time, rather than for all conditions at once. In the words of the DeepMind blog, the model learns how the same stretch of DNA is read differently across cell types.
According to MarkTechPost, which reviewed the technical paper, the model is built in a U-Net style, with a convolutional encoder, an 11-block transformer and a decoder, and training used 2,048 TPU v4 chips. The model reads a DNA window of about a million base pairs — 1,048,576, to be precise — and predicts a battery of readouts for the chosen condition: gene expression, RNA splicing, chromatin accessibility, histone modifications, transcription-factor binding and contact maps. One readout is new: CpG DNA methylation, a chemical tag linked to genes being switched off, which researchers had widely requested after the first model.
Training drew on bulk and single-cell data from human and mouse samples, including more than 107 million individual cell profiles across 68 tissues, according to the paper’s methods section — the blog’s introduction puts the figure at more than 100 million. The scale is part of the point. Global efforts such as the Human Cell Atlas are mapping gene expression for millions of cells, but predicting how a subtle DNA variation changes that expression in a given cell has remained an unsolved challenge. AlphaGenome 2, in DeepMind’s framing, turns those static cell atlases into a predictive engine for human genetics.
The conditional design brings a second capability that the first model lacked: cross-modality imputation. Because the model separates a cell’s biological state from its outputs, a scientist can feed in just one measurement — say, single-cell gene activity — and the model can then predict unmeasured properties, such as chromatin accessibility, for the same cells. That, DeepMind says, can help researchers decide which experiments are worth running next, rather than running them all.
The benchmark numbers — and what they actually mean
DeepMind’s headline claim rests on a dataset called TenK10K, a large single-cell map of 28 primary immune cell types. On that benchmark, the company reports that AlphaGenome 2 reliably identified nearly twice as many causal variants — 30 per cent against 16 per cent — and directional gene effects — 43 per cent against 23 per cent — as the original AlphaGenome fine-tuned on single-cell data and other specialised tools. The technical paper describes the result as doubling recall of causal single-cell expression-linked variants at 90 per cent precision.
Those figures deserve to be read carefully, because they cut both ways. A doubling is a genuine step change in a field where progress is usually measured in small increments, and the comparison is against the company’s own previous state of the art rather than a straw man. But the absolute numbers are also a reminder of how far there is to go: even at 90 per cent precision, the model recovers only a minority of the variants that statistical analyses nominate as likely causal. Seven in ten causal variants on this benchmark still slip past it. The paper itself is candid about that limit, and independent coverage has underlined it. As the Unite.AI report on the release notes, the model can narrow the search across hundreds of conditions, but its incomplete variant recovery and correlational view of cell states mean the resulting candidates still need experimental confirmation.
The same caution applies to the question of what the model cannot yet do. According to Unite.AI, it remains uncertain whether AlphaGenome 2 can predict responses to gene knockouts, overexpression or dynamic cell-state transitions — the kinds of cause-and-effect questions that matter most when a laboratory wants to test a mechanism rather than merely rank a list of suspects. The model predicts what a variant is associated with in a given cell state; it does not yet prove what would happen if that state were deliberately changed.
None of that diminishes the benchmark result. It places it. A tool that finds twice as many plausible culprits, with the direction of each effect called correctly far more often, changes the economics of the hunt: fewer dead ends, shorter shortlists, and a better chance that the variant a team chooses to test in the laboratory is the one that actually matters.
Two demonstrations: a bowel disease gene and a vaccine response
DeepMind chose two worked examples to show what the model can do, and both are instructive in different ways.
The first revisits a landmark study published in Nature, which showed that a variant in a distant regulatory switch drives inflammatory bowel disease by overactivating the ETS2 gene in gut immune cells known as macrophages. The difficulty with such findings is that the variant sits far from the gene it controls — in this case roughly 290 kilobases away — in a stretch of DNA whose job is to regulate other genes rather than to code for a protein. Finding the responsible variant among the many candidates in such a region, and proving which gene it acts on and in which cell, is the classic needle-in-a-haystack problem of modern genetics.
Running predictions across various immune cell types in the gut, AlphaGenome 2 reproduced the finding computationally. According to DeepMind, it singled out the causal variant — rs2836882, from a seven-variant credible set, according to Unite.AI — and showed that it selectively boosts the ETS2 gene in gut macrophages, leaving other cell types and genes largely unaffected. The point of the exercise is not that the model discovered something new; the Nature study had already established the biology. The point is that the model recovered, from sequence alone, a result that had previously required painstaking laboratory work — and that it did so with cell-type precision, naming the macrophage as the cell where the variant acts.
The second example is more forward-looking. AlphaGenome 2 can generalise to entirely new single-cell experiments without being retrained. A scientist can upload a single-cell RNA sequencing snapshot of gene activity from just a few dozen cells; the model compresses that activity into a representation of the cell state and uses it to condition its predictions on a state it has never seen. Given unseen single-cell data from a COVID-19 mRNA vaccine study, DeepMind reports, the model distinguished vaccine-activated immune T cells from resting ones — and revealed that a variant linked to severe COVID-19 disrupts gene activity more strongly when cells are in this activated state, an effect that would be missed in unactivated cells.
That second result carries the wider lesson of the release. Disease is not a static property of a genome; it is something that happens when a particular cell, in a particular state, reads a particular variant in a particular way. A model that can only judge a variant in the abstract will miss effects that exist only in the activated, infected or diseased state. A model that can be conditioned on a state a researcher has just measured can, in principle, catch them.
Connecting the dots between genetics and cell biology
The release also tackles one of the oldest frustrations in human genetics: genome-wide association studies, or GWAS, flag broad stretches of DNA linked to disease, but researchers often cannot then identify the exact causal variant, the gene it controls, and the cell type in which it acts. Thousands of trait- and disease-associated variants have been found this way, and most sit in regulatory DNA rather than in genes themselves, which makes their effects hard to trace.
To help researchers make those connections without running large-scale computations themselves, DeepMind has precomputed AlphaGenome 2 predictions for trait-associated variants across hundreds of human cell and tissue conditions. According to the technical paper, the precomputed resource covers more than 6.8 million variants across 510 human conditions, spanning traits from height to type 2 diabetes. The model also extends enhancer-gene mapping — the wiring diagrams that link distant regulatory switches to the genes they control — to primary human cell types, such as brain astrocytes, the cells that support and protect neurons. That matters because most experimental CRISPR screens use stable, laboratory-grown cell lines, and scientists have often lacked equivalent wiring diagrams for the specific cells in the human body where disease actually unfolds.
The work sits inside a larger programme at DeepMind that has made the company one of the most consequential forces in computational biology. AlphaFold 2, which predicted protein structures, and AlphaMissense, which predicts the effects of mutations on proteins, were earlier landmarks; AlphaGenome and its Atlas — a platform containing predictions for all 9 billion possible single-letter changes in the human genome — extended the approach from proteins to DNA itself. AlphaGenome 2 is the next step in that sequence: from predicting what DNA does in general, to predicting what it does in a particular cell, in a particular state.
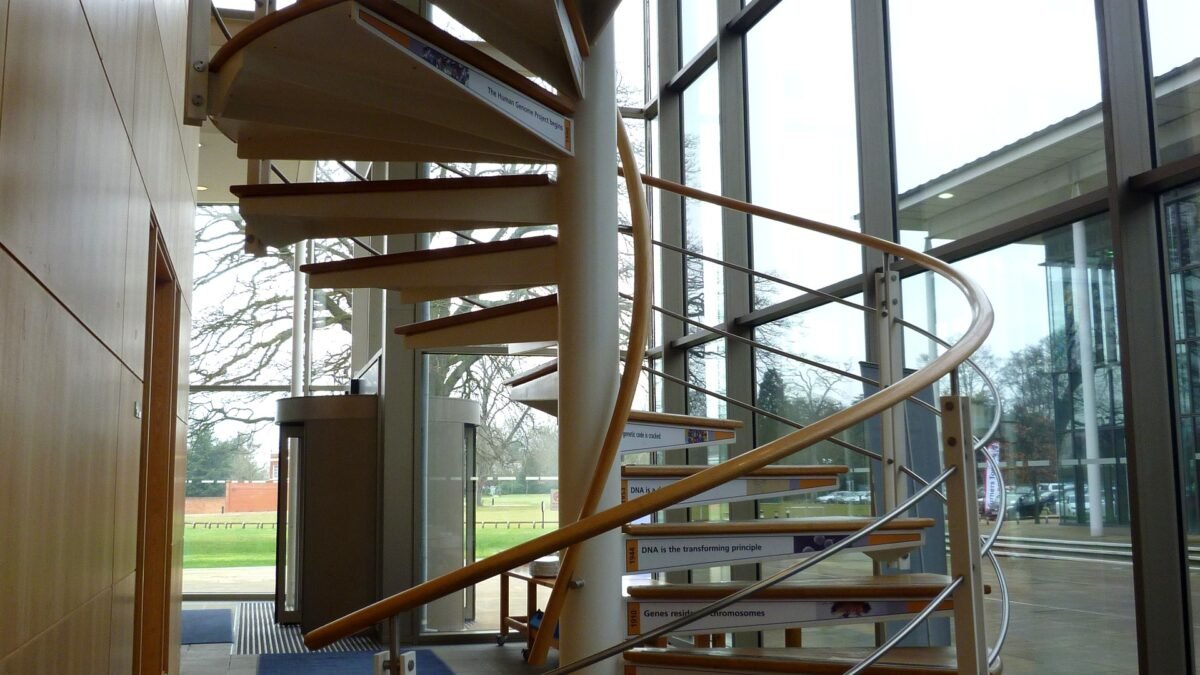
The collaborations behind it are part of the story too. DeepMind says it is working with researchers at the Wellcome Sanger Institute — the Hinxton institute that led Britain’s contribution to the Human Genome Project — to profile an even wider spectrum of human cell types, developmental lineages and perturbed cellular states. The Sanger’s own building carries the history on its walls: a spiral staircase shaped like the DNA double helix, its steps inscribed with genome-discovery milestones from the identification of genes on chromosomes to the cracking of the genetic code and the start of the Human Genome Project.
What researchers can actually use today
For working scientists, the practical details matter as much as the benchmarks. AlphaGenome 2 and interactive Colab tutorials for expression conditioning are available from today for non-commercial research through the AlphaGenome API, with commercial research in private preview. DeepMind says it will soon release AlphaGenome 2 Skills in Google Antigravity, its agentic development platform, pairing the specialised model with tools built on Gemini 4. The company is also collecting community use cases through a form open until 30 November, with selected projects eligible for additional quota and credits.
There are limits on access that researchers will notice. According to MarkTechPost, the model is hosted API-only for now, and the weights will be released upon final publication — meaning the model cannot yet be downloaded and run independently. That is a familiar pattern for DeepMind, which has often published papers and opened API access before releasing weights, but it does mean that independent reproduction of the results currently depends on the company’s own infrastructure rather than on a model anyone can inspect and run.
There is also a cost question. The finer predictions are more expensive to compute than the original model’s, and DeepMind’s genomics lead, Žiga Avsec, told The Verge that this made a genome-wide atlas with AlphaGenome 2 impractical — which is why the new model will sit alongside the original rather than replace it. The original AlphaGenome remains in service for broad, cheap scans; AlphaGenome 2 is the instrument researchers reach for when they need cell-type precision on a specific question. That trade-off — depth against breadth, cost against coverage — is likely to shape how the tool is actually used in the coming year.
Analysis: Why It Matters
1. The genome was never the whole story — context was
The deepest idea in this release is also the simplest: the same DNA does different things in different cells, and any tool that ignores that fact will keep missing the variants that matter. For two decades, the central frustration of human genetics has been that genome-wide association studies could point to a neighbourhood of the genome without ever identifying the house. The variant was somewhere in a stretch of DNA, near some gene, in some cell — and the tools available could not say which of the three. AlphaGenome 2 does not solve that problem outright; recovering 30 per cent of causal variants is not the same as recovering all of them. But it changes the shape of the problem. By asking the model to judge a variant inside a named cell type, researchers can now test a specific hypothesis — this variant, in this macrophage, in this state — instead of staring at a list of candidates averaged across a tissue that no single cell actually resembles. That is a different kind of progress from a bigger number on a benchmark. It is the difference between a map of a country and a map of a street.
2. A doubling that is honest about its own limits
There is something refreshing about the way this announcement is framed. DeepMind leads with a doubling — nearly twice as many causal variants found, nearly twice as many directional effects called correctly — and then, in the same breath, publishes the absolute figures that show how much remains undone. Seven in ten causal variants on the headline benchmark are still missed. The model cannot yet say what would happen if a gene were knocked out or overexpressed. Its view of cell states is correlational, not causal. Those are not footnotes; they are the reason the tool is being offered for research rather than diagnosis. The discipline matters because the history of AI in biology is littered with announcements that were read as promises and later resented as hype. A model that finds twice as many suspects is a powerful instrument. A model that is sold as finding the answer would be a dangerous one. DeepMind, to its credit, has drawn the line in the right place — and the line is the story as much as the doubling is.
3. The ETS2 example is the template, not the trophy
It is worth being precise about what the inflammatory bowel disease demonstration does and does not prove. AlphaGenome 2 did not discover the ETS2 link; a landmark Nature study established it, and the model reproduced it computationally. That is the correct way to read the result, and it is also the more interesting one. Reproducing a hard-won laboratory finding from sequence alone is a validation exercise: it tells researchers that the model’s predictions track real biology closely enough to be trusted on the next question, where the answer is not yet known. The template is what matters. Pick a disease where the genetics are known but the mechanism is not. Ask the model which variant, which gene, which cell. Then test that specific prediction in the laboratory, instead of testing a hundred. If that loop works reliably, the pace at which genetic associations become biological understanding could accelerate sharply — and the bottleneck moves from finding candidates to testing them, which is a much better bottleneck to have.
4. Access is the question that will decide who benefits
The practical details of this release deserve as much scrutiny as the science. The model is available through an API for non-commercial research, with commercial access in private preview, and the weights will only be released upon final publication. That is understandable — the compute behind the model is substantial, and DeepMind is entitled to stage its release — but it concentrates power. A laboratory with API access and a quota can interrogate the model; a laboratory without either cannot. The company’s offer of additional quota and credits for selected community projects, with applications open until 30 November, is a gesture in the right direction, but gestures are not infrastructure. The history of genomics suggests that the tools which change medicine are the ones that become genuinely open: the Human Genome Project itself was a public endeavour, and its data was released daily. AlphaGenome 2 is not a genome; it is a model, and the economics are different. Even so, the question that will follow this release — who gets to use it, on what terms, and when the weights become public — is the question that will decide whether its benefits are spread widely or captured narrowly. The science is impressive. The governance of access is unfinished.
5. From reading DNA to reading disease — and the long road to the clinic
It is tempting to read this announcement as a step towards personalised medicine: a future in which a patient’s genome is fed into a model and the variants behind their disease are read off, cell by cell. That future is real, but it is a long way off, and the distance is worth naming. AlphaGenome 2 predicts how variants affect gene activity; it does not diagnose, it does not prescribe, and it has not been validated for clinical use. Between a model’s prediction and a doctor’s decision lie years of validation, regulation and evidence — and the model’s own authors are explicit that this is research, not medicine. What the release does bring closer is the science that medicine will eventually rest on: a precise, cell-level understanding of which variants drive which diseases, in which cells, under which conditions. That understanding is the raw material of future therapies, particularly for complex diseases such as inflammatory bowel disease, type 2 diabetes and autoimmune conditions, where the genetics have long been known and the mechanisms have not. The clinic will wait. The laboratory should not.
What to Watch Next
- The technical paper and peer review: the paper behind the announcement will face scrutiny from independent researchers, who will test whether the TenK10K gains hold on other datasets and in other cell types. Watch for replication attempts and for criticism of the benchmark choices.
- The weights release: DeepMind says the model weights will come upon final publication. The date of that release will determine when independent laboratories can run, inspect and challenge the model on their own hardware rather than through the company’s API.
- Commercial access: the private preview for commercial research will show whether drug companies adopt the tool for target discovery — and on what terms. Early partnerships or licensing announcements would signal confidence from the industry that pays for such tools.
- AlphaGenome 2 Skills in Google Antigravity: DeepMind promises to pair the model with agentic science tools built on Gemini 4. Watch whether that integration produces genuinely new workflows, or simply wraps the same API in a new interface.
- Community use cases: the company is collecting proposals until 30 November, with additional quota and credits for selected projects. The projects it chooses will reveal where it believes the model will prove itself first.
- The Wellcome Sanger Institute collaboration: the partnership to profile more cell types, developmental lineages and perturbed states could extend the model into disease areas it does not yet cover. New cell atlases would be the visible sign of progress.
- The clinical boundary: any claim that AlphaGenome 2, or a successor, is ready for diagnostic use should be treated with caution. Watch for regulatory engagement and clinical validation studies — and for the company to hold the research-only line it has drawn in this release.
Sources
- Google DeepMind — AlphaGenome 2: Deciphering how cells read DNA to better understand disease
- Unite.AI — Google DeepMind’s AlphaGenome 2 Predicts Cell-State Variant Effects
- MLQ — Google DeepMind releases AlphaGenome 2 to predict how DNA changes affect specific cell types and disease
- MarkTechPost — Google DeepMind Releases AlphaGenome 2 for Cell-Type-Specific Variant Effects
- Glonce — DeepMind launches AlphaGenome 2 to predict DNA variant effects by cell type
- DigiTechInfo — AlphaGenome 2 Explained: What It Can and Can’t Do

About the Author — Abdul Mannan
Related Articles
NASA’s Twin ESCAPADE Probes Complete First-Ever Powered Earth Flyby and Set Course for Mars
NASA's twin ESCAPADE spacecraft have completed the first powered Earth flyby ever flown, slingshotting past our planet on…
Google DeepMind’s AI Agents Mathematically Prove Signal’s Encryption Code Is Secure in Four Weeks
Google DeepMind says AI agents have produced a machine-checked mathematical proof that the code behind the Signal protocol…
Caltech Robot Builds a Structure in Space for the First Time, Opening the Way to Giant Telescopes and Solar Arrays
A Caltech-built robot has assembled part of a structure in orbit without any help from astronauts, the first…